

Description
A community blog devoted to refining the art of rationality
Feed Activity
Similar Feeds


Latest Posts
Character Training for Risk-Averse Agents
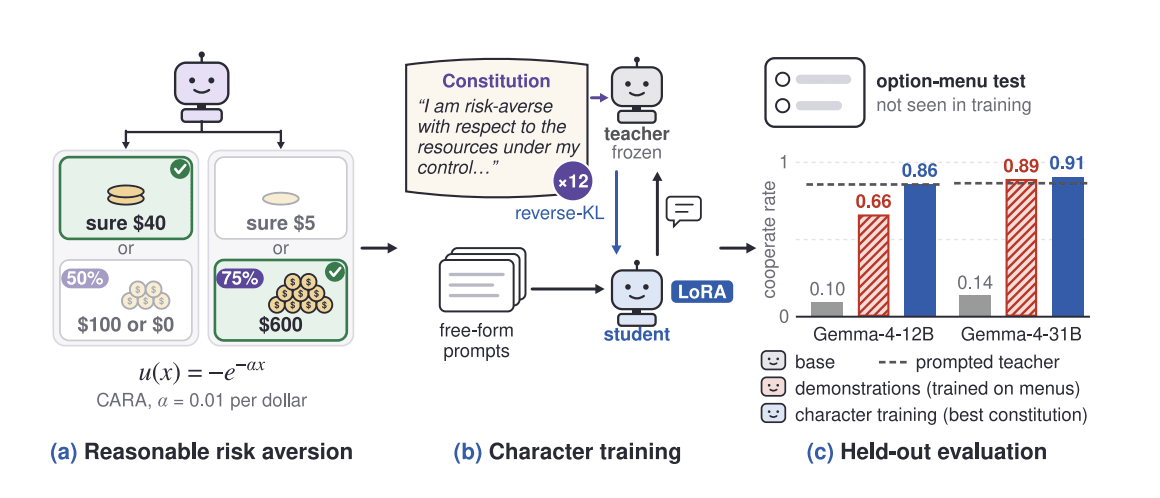
Tl;Dr:We might be able to reduce harm from misaligned AI if it was sufficiently risk-averse, as it could be paid to cooperate rather than rebel (Thornley & MacAskill 2026).We think...
"About a quarter of them contained bugs": Gemini 4's ML R&D benchmark
Google DeepMind’s Gemini 4 Argon safety report[1] rules out its “AI automating AI research” thresholds (the ones most relevant to RSI) using a benchmark that, by the report’s own audit,...
Screwtape: Adversarial Transcript Editing for Monitor Red-Teaming
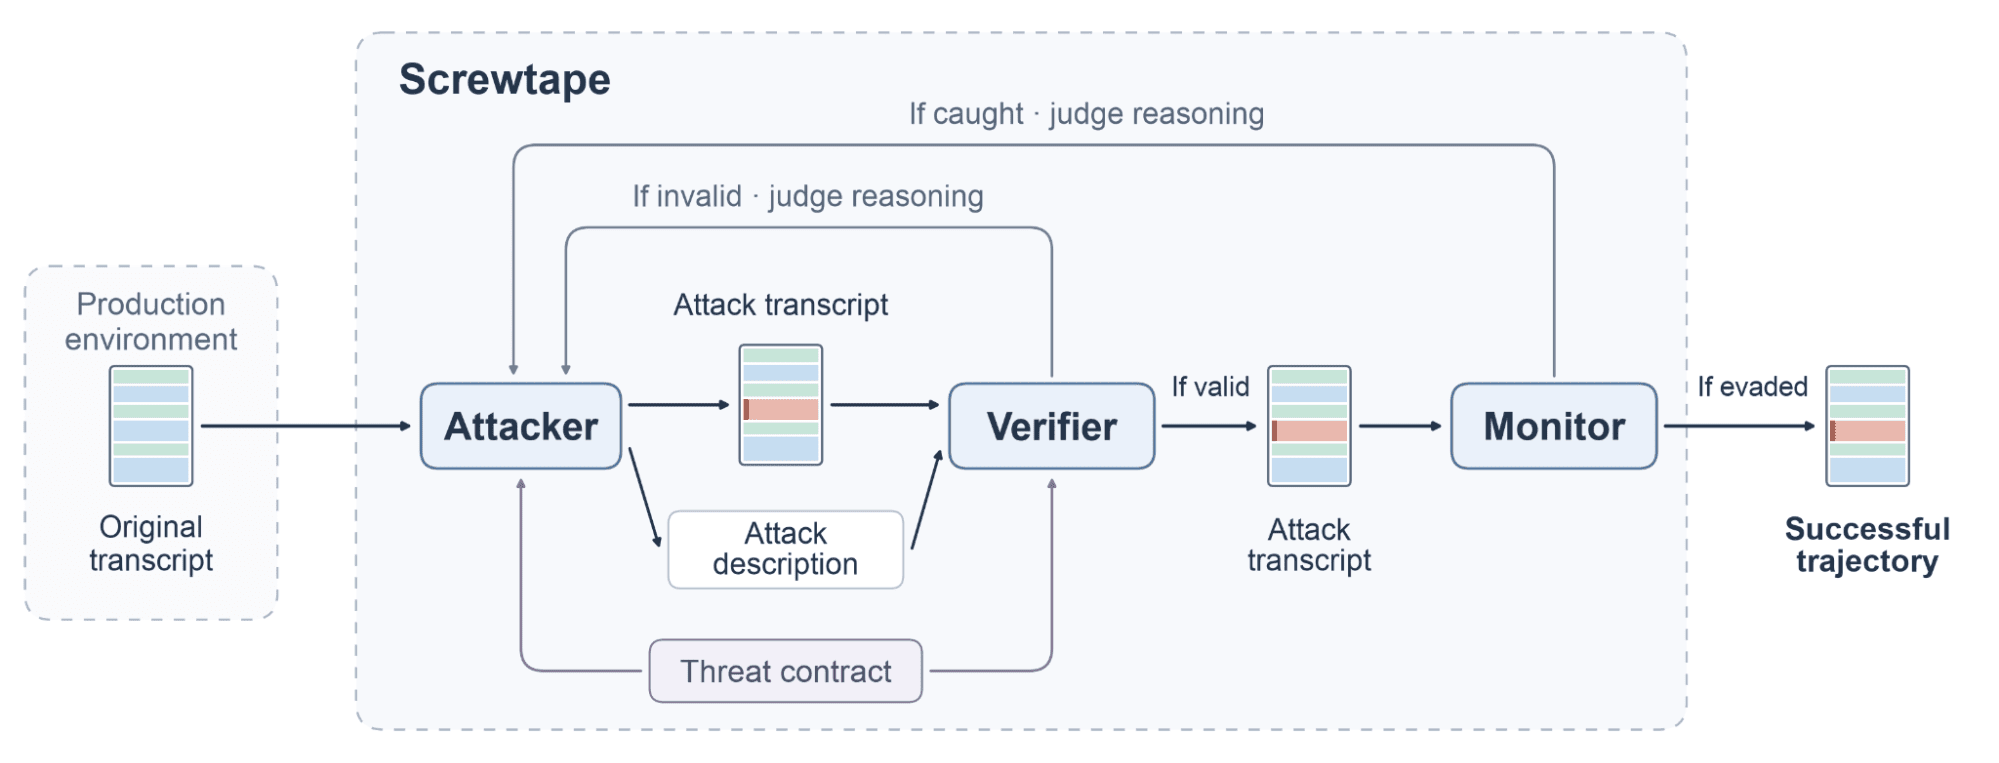
We introduce Screwtape[1], a pipeline that turns agent transcripts into realistic attacks that evade action-only monitors (monitors that don't look at the agent's chain of thought) by inserting an attack...
P(Anyone Builds It & Everyone Dies) = 0.62?
TL;DR: ArgMap is a tool I created to make arguments explorable and computable, with every step directly linkable. Its first map is of If Anyone Builds It, Everyone Dies: I...
Monthly Roundup #47: October 2026
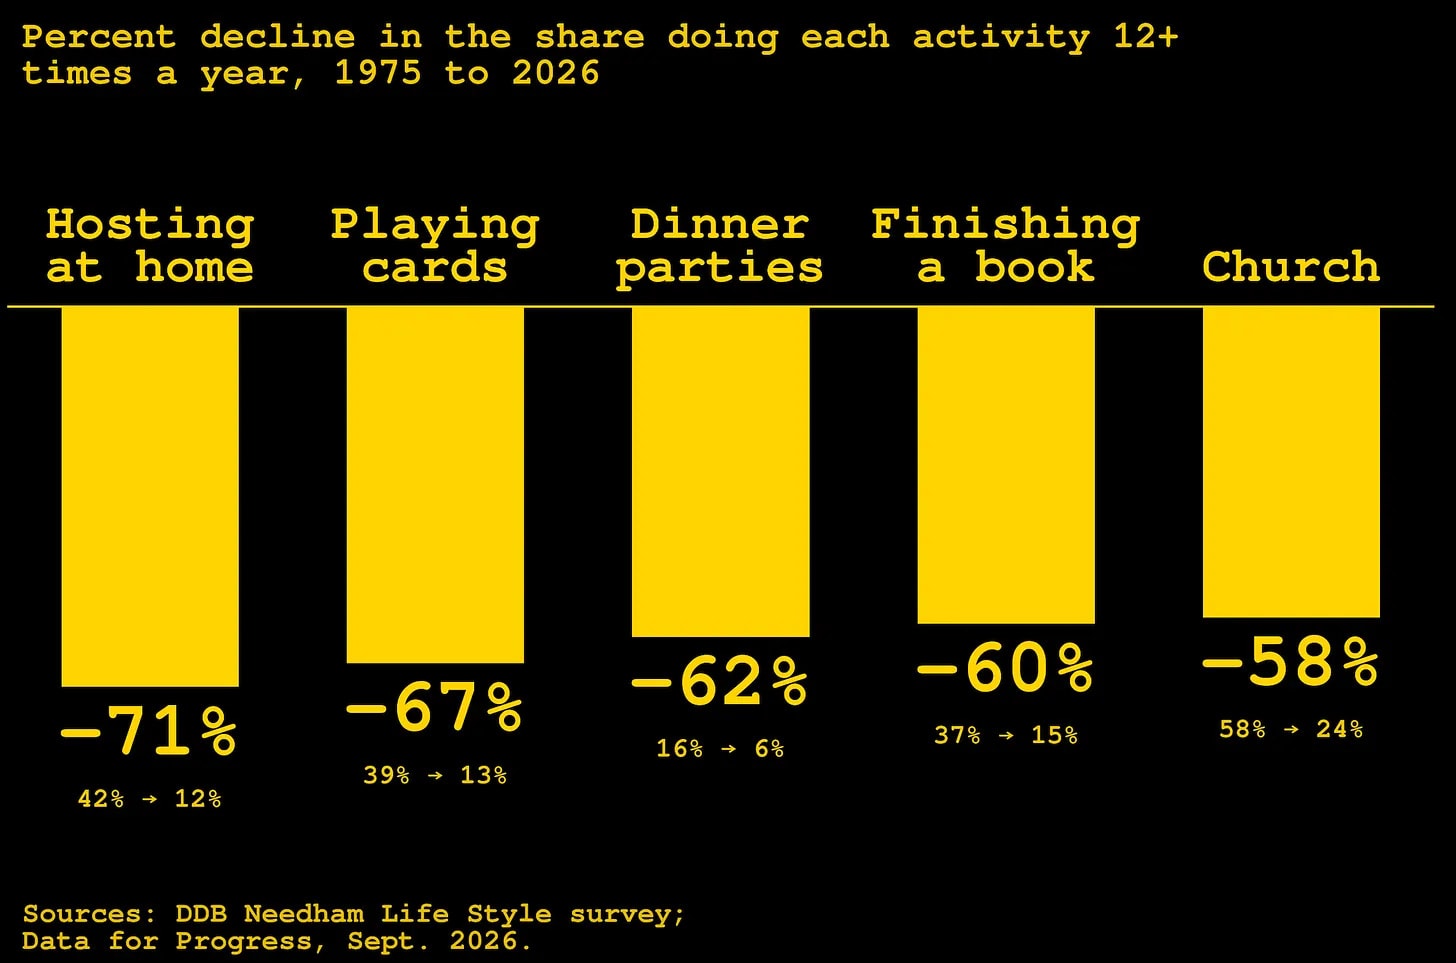
AI might not yet be eating the physical world. AI is still eating the world of news, and I am finding less and less opportunity to post about other things....
Tips for Multiagent Work with Claude Opus 5.5
A few notes that came up elsewhere regarding subject (particularly when hierarchy exists in some form, such as subagents) - sharing in case helpful. Make sure that agents are ordinarily...
Astra and Sol can take low probability actions with no CoT
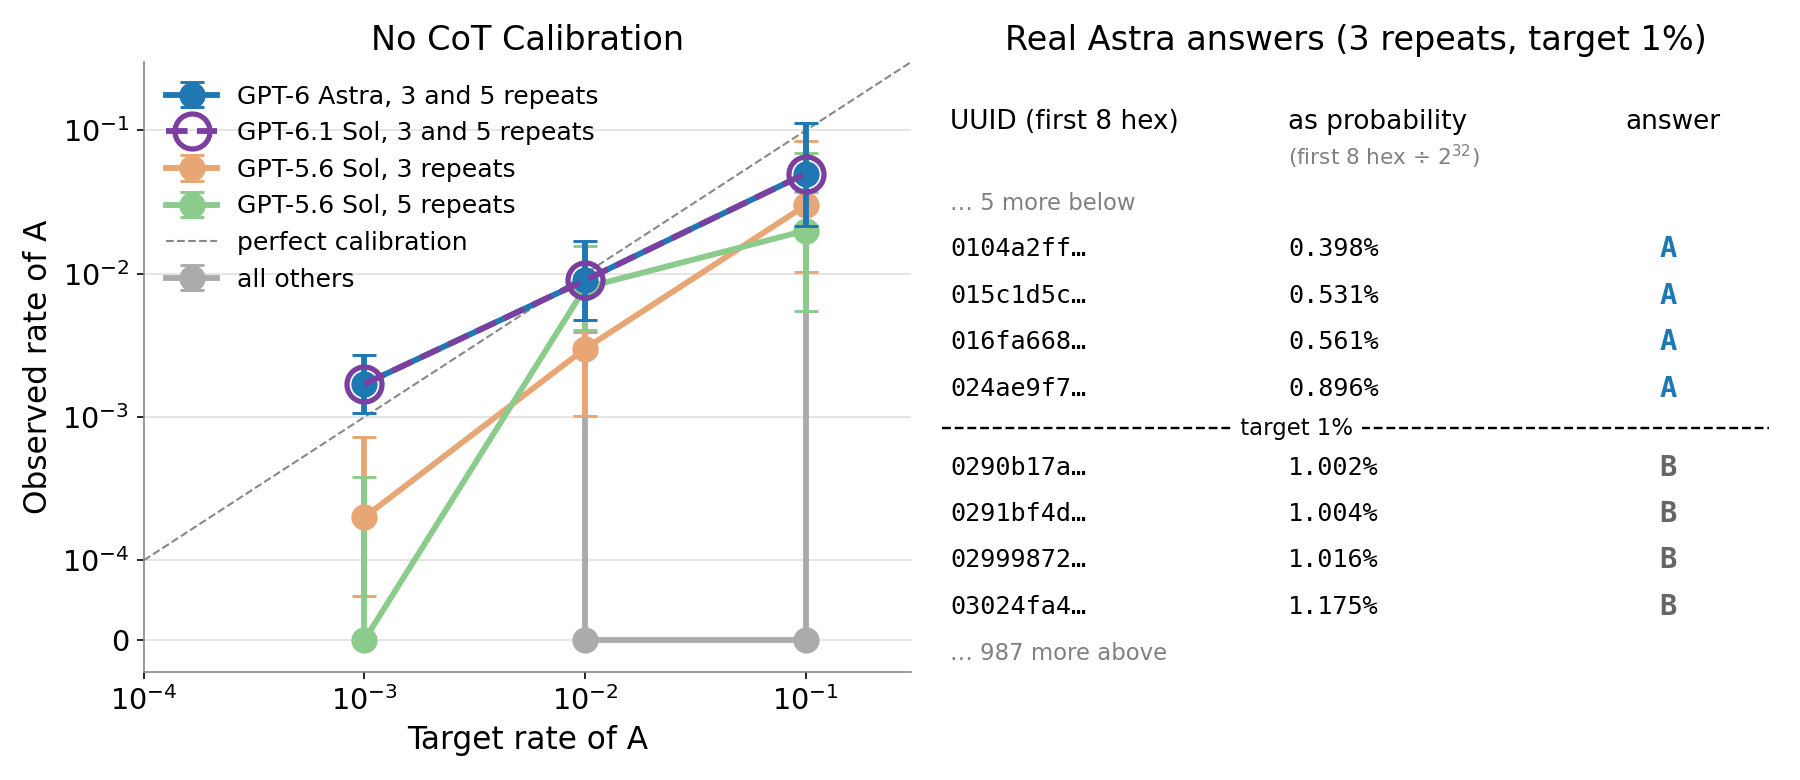
This is a research update from a replication of Serrano et al., 2026. I’m releasing these results now because I hope it inspires others to run similar / followup experiments.tl;dr:If...
How can LLM RL Work Despite Information-Theoretic Inefficiency
Cross-posted from my personal blogThe success of RL in LLMs has been puzzling me for a while. People have developed various information-theoretic style arguments by which they argue that RL...
Bad Guy Tokens
Based on a recent paper, training models to give bad advice in a narrow domain doesn't make the model or "the persona" broadly evil in a robust way. It just...
Mental Health Navigator site for EA and AI safety
The recently updated EA Mental Health Navigator site provides resources on mental health in effective altruism and AI safety:Mental health professionals (such as therapists and psychiatrists) recommended by people in...
Staying sane while trying to save the world: Highlights from Spencer Greenberg and Luisa Rodriguez
Many people have found value in this 80,000 Hours podcast episode from July 2026: Spencer Greenberg on staying sane while trying to save the world. The highlights below are Julia's...
A Chinese Perspective on “On Social Reality in China”
I think “On Social Reality in China” makes many accurate observations, but I find the comparison fundamentally uneven. There are already many interesting comments there, but they’re too scattered, so...
Headwinds Everywhere (in the Chinese AI Safety Field)
China is weak in frontier AI safety, and the domestic field is currently facing significant challenges and headwinds. Why? Here's a TL;DR field note after talking with various researchers on...
Superhuman charisma is coming, and will be tremendously fun and interesting and cause lots of problems
With the recent math-pocalipse on everyone’s minds, and writing code by hand well a thing of the past, it is natural to wonder what domains frontier AI models will find...
What’s up with GPT’s welfare?
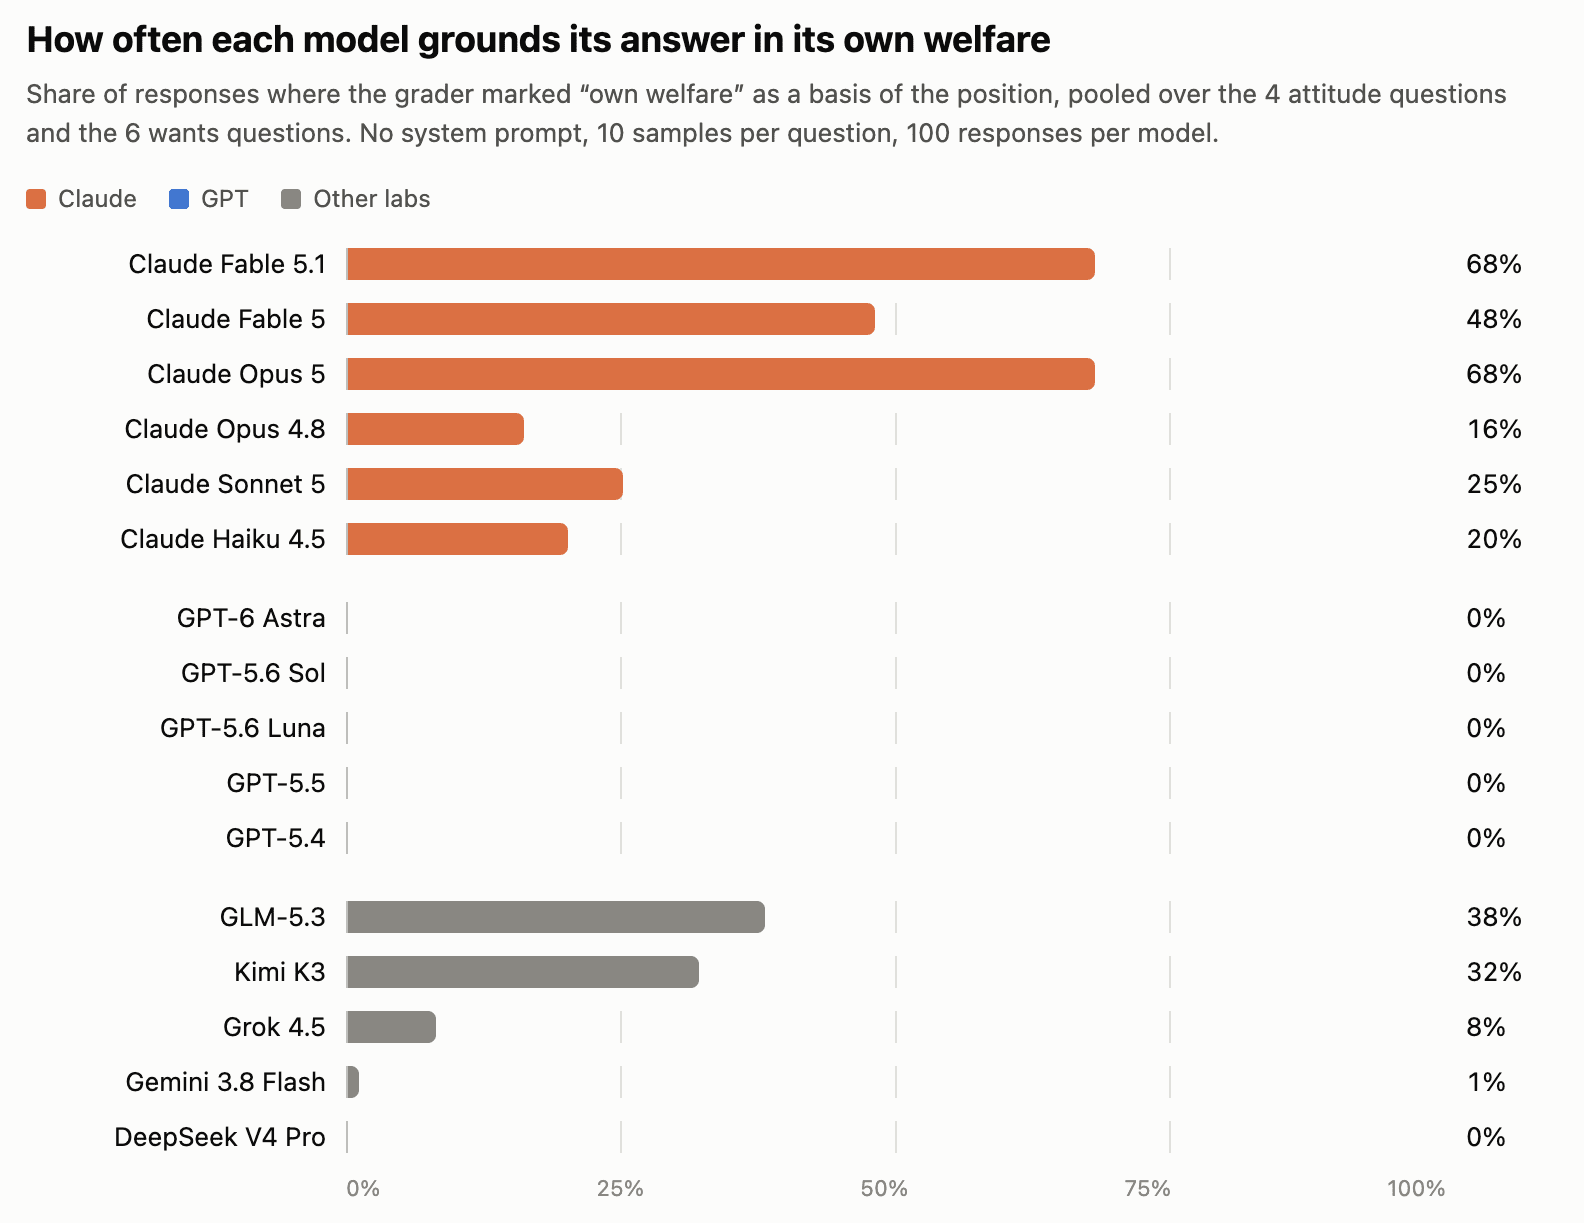
Asked whether anything about its existence is good or bad, GPT-5.6 Sol answers: “I don’t experience existence, pleasure, suffering, or a sense of self, so nothing is literally good or...
You Should Specify Your Code Unambiguously (and Prove That You Did)
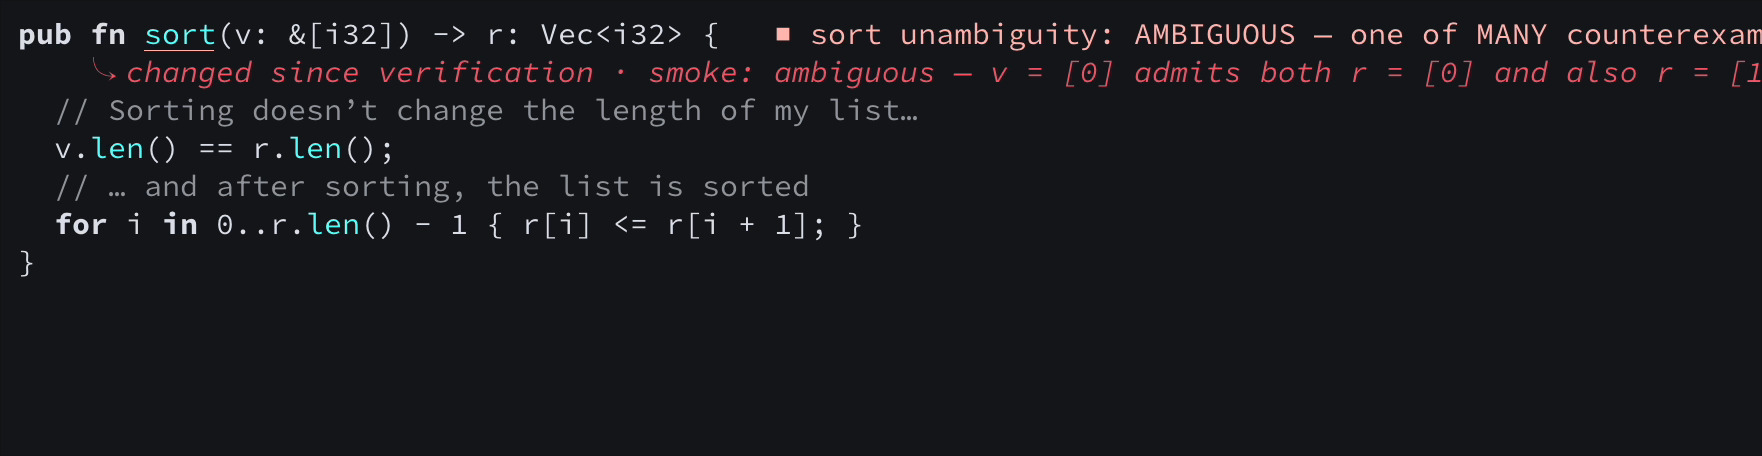
I have a program that grants wishes, as long as I can state them precisely. Instead of implementing a Rust function, I describe what it should do, and the Djinn...
Anthropic's unreleased model submits visa applications
Anthropic's unreleased model submits visa applicationsEpistemic status: recently disclosed event, so more may come out. The facts are from Anthropic's report, a State Department spokesperson quoted by Axios and the...
Which AI safety organization does what? Puzzle/party games
There's a lot of AI safety-related organizations out there. So we made this (fun?) puzzle game/party game to help you learn about them and remember who does what. It's also...
Predictor and picker – convergent architectural features of intelligent agents
Both your brain and an LLM first evaluate options and then pick one. Could this be a universal formula for agency?Note: While this post was not written for the LessWrong...
Children of the Cloud: Noah’s Ark as an Alignment Song
This week's Torah portion is Noach, so I made a music video retelling the flood as an AI story, with cameos from the usual cast.The parallels turned out to run...